Wednesday, August 10, 2016

Best of July


I found the blog "The morning paper", very good. There was a series of papers about chatbot development. The blog is changing topic often by reviewing papers from actual conferences but there are several interesting ones even if it's not about chatbots. Anyway here is the selection about "chatbot" papers:


Chatbots are not good enough (yet) to replace humans so why do not automate human workforce. Scale (http://www.scaleapi.com/) is a startup who want's to do this. Let get done short tasks by human workers through API calls.

And finally some marketing related infographics from Kissmetrics I came by during the month: How to calculate customer lifetime value:
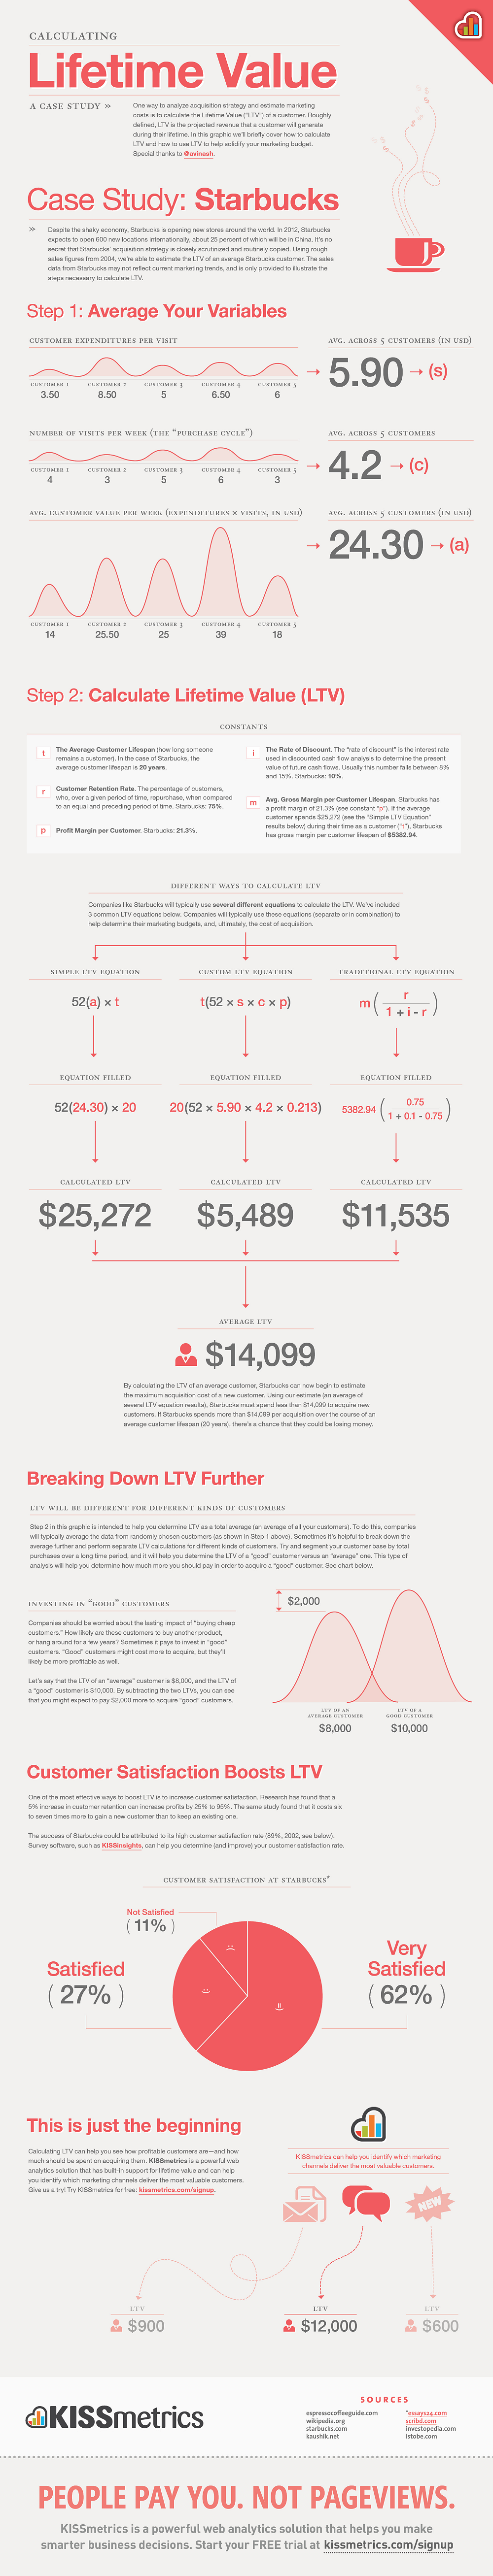
How To Calculate Lifetime Value – The Infographic

Wednesday, July 13, 2016

A more comprehensive list of conversational datasets

The list just the copy of the datasets listed in A survey of available corpora for building data-driven dialogue systems (Serban et al. 2015). All credits goes for them. I simply try to make it more accessible. I couldn't find the download location for every one of them, so if you see a '?' as URL and you know how to get the data, please write a comment about it.

(same google doc as a link)

Monday, July 4, 2016

Best in June

As last month I posted a video about "hyper reality" I also found a writing about "hyper personalization". For me this is just personalization but either way we call it I agree that tere is a move in this direction:
Focus on 3 important ‘W” of hyper-personalization:
  • Who you personalize
  • What you personalize and
  • Where you personalize.
 Anyway, let's switch back to my favorite topic these days, chatbots :) I found a page, it's not exactly about chatbots, but it shows how interesting this simple chat interface can be. There is a weekend project to post interviews as chat one-to-one chat dialog. Check out Talk turkey!

And finally I found a pretty comprehensive list of dialog datasets. I found it in this article: A survey of available corpora for building data-driven dialogue systems (Serban et al. 2015). If you don't want to read the whole 46 pages (btw it's probably worth for you if you are interested in developing chatbots) I'm still processing the list but I will make it available in a separate post soon.

STRATA + Hadoop world London was organized in jun. If somebody missed the keynote from Stuart Russel, I recommend to watch it. He is talking about The future of (artificial) intelligence.

#FUN: And you can also check http://www.projectmurphy.net/ Microsoft's AI bot:
With the Bot Framework you can add the bot on Skype, Messenger, telegram etc.. and ask it all life's most important questions such as: "What if Charlie Chaplin was a baby?" or "What if Beethoven was a rockstar!" Project Murphy then uses artificial intelligence to answer these questions by combining the subject's face with the object of interest i.e. a baby's face smartly added on top of Charlie Chaplin's face.

Thursday, June 16, 2016

Best in May

In may there was just a couple of stories grabbing may attention. Here are those:


And here is a movie about augmented reality. As I'm working with personalization in retail space, it was particularly interesting for me.

Sunday, May 1, 2016

Best in April

Still chatbots and more. Sundar Pichai said this last week on Alphabet’s earnings call:
In the long run, I think we will evolve in computing from a mobile-first to an AI-first world.

Reinforcement learning toolkit for Python: OpenAI Gym

Speech KITT makes it easy to add a GUI to sites using Speech Recognition. Speech KITT provides a graphical interface for the user to start or stop Speech Recognition and see its current status. It can also help guide the user on how to interact with your site using their voice, providing instructions and sample commands.
Rod Humble had previously spent three years as the CEO of Linden Lab, and before that worked on the Sims franchise as an EVP at Electronic Arts. In June, an automated conversation company called PullString (formerly ToyTalk) hired him to create a new series of games for Facebook Messenger called Humani. Here is a nice article about this game: Humani: Jessie's Story.

Tuesday, April 19, 2016

Chatbot craze - deep learning for chatbots intro

I'm just participating the Deep Learning Udacity course (I really like it :) When I found an article: Deep Learning for Chatbots, Part 1 – Introduction. Exact the topic I'm really interested in.

It's a nice introduction. And it sheds some lights on the capabilities of the state-of-the-art systems. E.g.: "However, we’re still at the early stages of building generative models that work reasonably well. Production systems are more likely to be retrieval-based for now."

Also I found interesting references about incorporating context into generativ models: "Experiments in Building End-To-End Dialogue Systems Using Generative Hierarchical Neural Network Models and Attention with Intention for a Neural Network Conversation Model both go into that direction."

Sunday, April 17, 2016

Question Answering datasets

To extend the list of conversational datasets there is a collection of Question Answering (QA) datasets. A question-answer pair is a very short conversation which can be also  used to train chatbots. If you want to use the chatbot for giving information for customers, like automated customer support or automated sales agent on your website, this type of datasets can be particularly useful.

The WikiQA corpus is a new publicly available set of question and sentence pairs, collected and annotated for research on open-domain question answering.

Usually on TREC (Text REtrieval Conference) there is a QA task which has some kind of datasets associated with it. Most of the datasets are focusing on factoid QA task but the one in 2015 is a kind of live QA. The task was to answer questions on Yahoo Answers.

Manually-generated factoid question/answer pairs with difficulty ratings from Wikipedia articles. Dataset includes articles, questions, and answers.

There are some manually curated QA datasets from Yahoo Answers from Yahoo.

You also can download the Stack Overflow questions and answers. It's a domain specific but huge dataset.

Saturday, April 9, 2016

Conversational datasets to train a chatbot

As in the last two months I read a lot about chatbots which awakens in me the desire to develop my own chatbot. And of course the most trendy approach is some deep learning. That's why as a first step a decided to collect the available conversation datasets which are definitely needed for training. Here is the list of English conversation datasets I found: (If you know about more please leave a comment.)

Data collected from twitter (by Chenhao Tan):


  • Argument trees, "successful persuasion" metadata, and related data from the subreddit ChangeMyView. First release 2016.


  • Multi-community engagement (users posting, or not posting, in different subreddits since Reddit's inception). Data includes the texts of posts made and associated metadata, such as the subreddit, the "number" of upvotes, and the time stamp. First release 2015.


  • Cornell natural-experiment tweet pairs: data for investigating whether whether phrasing affects message propagation, controlling for user and topic. zip file can be retrieved from the given URL (first release 2014)


  • Supreme Court dialogs corpus: conversations and metadata (such as vote outcomes) from oral arguments before the US Supreme Court (first release 2012)
  • Wikipedia editor conversations corpus: zip file can be retrieved from the page I've linked to (first release 2012)
  • Cornell movie-dialogs corpus: conversations and metadata (IMDB rating, genre, character gender, etc.) from movie scripts (first release 2011). This corpus contains a large metadata-rich collection of fictional conversations extracted from raw movie scripts: 220,579 conversational exchanges between 10,292 pairs of movie characters.
  • Microsoft Research Social Media Conversation Corpus. A collection of 12,696 Tweet Ids representing 4,232 three-step conversational snippets extracted from Twitter logs. Each row in the dataset represents a single context-message-response triple that has been evaluated by crowdsourced annotators as scoring an average of 4 or higher on a 5-point Likert scale measuring quality of the response in the context.
  • And a conversation on Reddit about a Reddit corpus.
  • The Santa Barbara corpus is an interesting one because it's a transcription of spoken dialogues.
  • The NPS Chat Corpus is part of the Python NLTK. Release 1.0 consists of 10,567 posts out of approximately 500,000 posts we have gathered from various online chat services in accordance with their terms of service. Future releases will contain more posts from more domains. 
  • NUS Corpus is a collection of SMS messages. There is English and Chines corpus as well.


  • Off: during my research for conversation datasets I found a relatively large collection of public datasets here .

    EDIT: you can also check the collection of QA datasets.
    ALSO CHECK OUT THIS more comprehensive list of dialogue datasets.

    Best in March

    This month is still about AI more specifically about chatbots. There was so many news about this:

    Techcrunch wrote that Facebook’s Messenger Bot Store could be the most important launch since the App Store.

    Tay, Microsoft's AI Twitter chatbot got racist.

    PocketConfidant developed an AI for coaching through a chat interface.

    Robot At SXSW Says She Wants To Destroy Humans ...

    There was more companies on Y-combinator's demo day dealing with this topic:
    • Nova uses artificial intelligence to write sales emails automatically. It can search the web and social media for facts about the recipient that it can include in the email, like that they were recently the subject of a news article, or enjoy a specific hobby. Nova’s emails perform better than humans. They get a 67% open rate and 11% click through rate.
    • MSG.ai helps onoperating chatbots on multiple platforms. It offers a centralized dashboard to detect trends and sentiments, and integrates with Salesforce Desk and Zendesk. With Msg.ai’s intelligence and A/B testing, businesses can maximize the benefit of their chatbots.
    • Sendbird provides a UI, SDK and backend to easily add chat functionality for websites and apps.
    • With Chatfuel, those looking to build and engage an audience can use the native interface to create bots that help facilitate conversations. More than 130,000 bots have been created on the platform. Publishers, like TechCrunch and Forbes, can build on Chatfuel and deploy to any messengers.
    • Promt is a chatbot building platform that lets businesses build a chatbot in 15 minutes with 15 lines of code. It can then be deployed instantly to Slack, Line, WeChat, SMS, and soon Facebook Messenger.

    Sunday, March 13, 2016

    Best in February

    I'm reading many interesting news and articles on the web and it's so hard to find them later that I decided to collect the best ones in a post at least once a month. Just a short summary and the link to the original article. If you have similar interest it will be probably a good collection for you too.

    Tensorflow: the python deep learning framework from Google. Probably it's not so polished as Theano a widely used Python deep learning library but for me it's much easier to understand and write code in it. And if you want to learn it, here is a great tutorial. And there is also a tool where you can use Theano or Tensorflow through the same interface.

    The zero UI is the new trend. I love it. Use chat or SMS as a communication interface. Here is a blog post and an other article about this. Big companies are trending in this direction. The only obstacle what slows down the progress is that machines are not yet able to understand human language. But there is so many development in this direction that in a couple of years I expect a significant breakthrough in natural language understanding. (And here is where singularity come into the picture...)

    Just for fun: you can live inside Van Gogh's famous painting thanks to the Art Institute of Chicago.

    Wednesday, April 16, 2014

    The data or the story convince us?

    Interesting video about how data should be presented.
    Most organizations recognize that being a successful, data-driven company requires skilled developers and analysts. Fewer grasp how to use data to tell a meaningful story that resonates both intellectually and emotionally with an audience. Marketers are responsible for this story; as such, they’re often the bridge between the data and those who need to learn something from it, or make decisions based on its analysis.


    Also worth to check: http://futureofstorytelling.org/

    Sunday, January 19, 2014

    Biking in Budapest - moonbike.co

    Here is my small side project: moonbike.co. I really like biking and I tried to collect all bicycle shops in Budapest and putting it on a map. Nothing complicated. I only wanted to have an easy to use collection of this shops because all similar site I found are crappy.

    If you know a bicycle shop which is missing from my list, please email it to info@moonbike.co :)

    Sunday, November 24, 2013

    Building a successful product

    “The goal of a startup is to find the sweet-spot where minimum product and viable product meet — get people to fall in love with you. Over time, you listen to your customers, make improvements and raise the bar on what viable means — making it more expensive for competitors to jump in.” – John Radoff
    There is a worth to read post about how to develop a product from a beginning. Here are my favorite points:

    You don't have to be afraid to start small:
    ...We heard no outcry from customers who felt shortchanged by our tiny product, because we were selling something that does what it says on the tin; our marketing and sales were aligned with the product itself. We found, however, that those initial customers were delighted as we started to add new features based on their feedback...
    Then you should select the new features carefully:
    Listen To The People Who Are Willing To Pay For Your Product ... There will be no end of people who are keen to tell you exactly what you should build them for free.
    Clearly understanding your core use case — the initial problems your product is intended to solve — is vital to deciding which features to add to the product.
    And finally do not expect big increase in sales numbers after developing a new feature:
    It took me a long while to learn that adding new features is not a huge marketing win in itself. We’ve added some huge and much-requested features to Perch over the years. Many of those features took as long to build as developing the initial product did. However, launching a new feature has never made a blip in our sales figures.
    ... pinning your hope of acquiring new customers on some new headline feature is not realistic in my experience. Instead, focus on marketing activities and on finding new customers and users, in addition to developing new features.

    Friday, October 4, 2013

    Visual story about a Zebra (d3.js + animal movements)

    I was on adding some data related cover image to this blog and I found a database about animal movements.  They are tracking several animals all over the world and the tracking data is publicly available. After short browsing I downloaded the track record (.csv) of a Zebra in the heart of Africa.

    As I was interested only in the time and position data I made some preprocessing in python. The final output was 4 data columns: the longitude, latitude, the seconds to the next tracking point and the hour if the day. I included the sample code if you are interested in the details:


    Finally I just included the result in the JS file as a JS array. After we have the data points in an array it's quite easy to draw the tracking points. Of course I wanted to use d3.js as it is my favorite visualization "tool" :)

    The idea was not just simply draw the points but additionally:
    • Small arrows display the directions.
    • The size of the points are the function of the time elapsed to the next tracking point. If the tracking points are recorded more rarely the points are bigger.
    • The color of the points depend on the time of the day when the tracking events were recorded. Green for the early morning, yellow for morning, orange around noon, read for the afternoon and purple for nigth.
    So instead this:

    Something like this:

    Datails about the d3.js code:

    Nodes are generated with gradients to make them really nice. And also partially transparent to visualize overlapping. Here is a magnified part:


    This circles are drawn like this:
    The connection of the circles was a bit mor complicated. Originally I intended to use svg path for the lines, but with it I had problems to drow the small arrows so I had to draw each line separately.

    You can check the endresult in the header ;) It was also interesting to see that the visualization inspired ideas about the locations: The big yellow and orange circles are located mostly around a limited area in lower middle part. Probably there is a pasture or some water where is a good place for the zebras to spend the day. Interestingly the zebra is wandering a lot in the night and early morning. I also think they are sleaping at a different location than they are spending the day at. Of course this are just presumptions but it was good to see that a more sofisticated visualization can tell so much more about the data.

    The full image:

    Wednesday, October 2, 2013

    Upside down funnel 2: satisfied customer leads to leads

    “I told my friend that we discovered this “upside down funnel” approach in the early days, and never really grew out of it (because it’s worked). When you see our strange billboards that don’t even say our name, or when you see our random “high five” shirts, vinyl toys, or hear ridiculous radio ads, just know that they defy logic because they’re for our existing customers. We’re not going for new leads, let alone conversions or whatever they teach you in Marketing 101. We’re going for customer service. Which, by the way, leads to leads.” - Ben Chestnut, Co-Founder Mailchimp
    Read Ben’s full post. It’s wonderful.

    Wednesday, September 11, 2013

    The engagement pyramid - flipping your funnel upside down

    So, why don’t we flip that 100% winnowed to 30% winnowed to 5% funnel? Rather than starting by thinking about how to reach or broadcast to as many people as possible to get to those who matter, what if we began with engaging those who matter the most. We could prioritize surfacing the 5% — and make our entire plan better by learning from their interactions and leaning on their advocacy to expand our reach in a smarter way... 
     By turning the reach-driven funnel upside down, we’re in effect creating an ‘engagement pyramid’. The engagement pyramid isn’t just about retention and growth of our existing customer base. It’s about starting with the 5% who will be most interested in what we have to say and most willing to speak for us. This group not only includes current customers, but also those most likely to influence others toward your brand. This is the group whose insights and advocacy can better inform and enhance our broader media plan, maximizing our overall engaged reach.


    read more: the engagement project (google)

    Sunday, September 8, 2013

    Correlation of investment funds - python pandas

    While playing around with python data mining framework Pandas I really liked how easy it is to calculate pairwise correlation in data series. Let's check out a sample. As data we can download historical investment fund data and we will calculate the correlation between them.

    note 1.: If you are using windows the easiest way to install python with every necessary packages is the Anaconda distribution. Just download and run the installer from here and you are ready to start :)


    note 2.: It wasn't easy to find historical data about investment funds. Finally I get the data from Bloomberg website. It was a kind of reserve engineering by checking the network communication when the site was drawing the graphs so there is no warranty that the data format won't change in the future. If somebody know better way to get this data I would be happy to hear about it.

    Let's download first the data into an array:


    Now we load it into a Pandas DataFrame and plot it (maybe you have to import matplotlib first):


    The two dataframe has to contain data for the same period of time so we can simply merge them:

    The result is:

    Finally let's calculate the correlation:

    And we get the pairwise correlation of the numeric columns:

    Friday, August 30, 2013

    Django unchained - python in the cloud

    I was experimenting with the django web framework. First I found this helpful tutorial: http://effectivedjango.com/tutorial/getting-started.html. I really liked that it's starting from the basics which makes it usable for python beginners too.

    After reading the tutorial I wanted to create a django project in the cloud. My first idea was to use Google App Engine because it has python support and it's free for small projects. I found this tutorial http://www.allbuttonspressed.com/projects/djangoappengine about running django projects on Google App Engine but I realized that I have to extend django with support for non relational databases. I found this step a bit complicated. There was an other tutorial to run django with Google Cloud SQL but it turned out to have no free version.

    So keep the story short after spending several hours to find out how to run my django project on Google App Engine I find myself in searching for other free django hosting solutions. And I come across pythonanywhere.com and it was a really nice surprise for me. It doesn't have so many features like Google App Engine but it's optimized for python. I finished the registration in 5 minutes and it was really easy to find a description how to run django project here (https://www.pythonanywhere.com/wiki/DjangoTutorial). It took me just 30 minutes to configure everything end write a hello world application from the scratch in their in browser console (yes, they have an in browser bash console) and open it in my browser for the first time.

    So just to summarize my positive impressions about pythonanywhere.com:
    • free plan with mysql support
    • web based bash console
    • really easy to set up
    • good tutorial (first I missed how to refresh the server, but it was just at the end of the tutorial)
    • they have dropbox sync which makes synchronization very straightforward
    • easy way to check access and error logs
    I also heard good things about heroku. They also have a good getting started guide. Maybe worth to try it as well:  https://devcenter.heroku.com/articles/django

    Additionally here is a really short introduction video:

    Tuesday, August 13, 2013

    Simple A/B test in Google Analytics

    Google has it's A/B testing solution called "Content Experiments". Originally it was designed to test different page alternatives. In this case you had to build two different version of the whole page or website (link). This can be quite complicated. Google announced his new "Content Experiment API" which is more flexible but for me it's also a bit complicated for very simple tests. On the other side there is a really simple way to implement A/B tests on a website. Let's see how!

    For the A/B testing we will use a couple of lines of JavaScript code. You can do any kind of split on your users but for now we will use a simple random split. The result of the split is stored in a long living cookie.


    After having the A/B test cookie, the only thing you have to do, is changing your site behavior based on the cookie and passing the group value to the Google Analytics.
    Very simple content experiment. ]]>
    To have the same groups in the Google Analytics you only have to add this two lines to your original GA tracking code (more description in GA help): ]]>
    To check the result in GA you only have to define custom filters in GA. Here are some screen shots how to do this:


    Sunday, July 21, 2013

    Vectorize Image with Python scikit-image

    Short story: a friend of mine wanted to display an interactive dental chart on the web but most of the images he found was some hand-drawn image which wasn't fit into his site look-and-feel. So decided to vectorize one image, it shouldn't be a hard task ...
    After some research I end up here:  http://scikit-image.org/docs/dev/auto_examples/ and I succeeded to get vectorized outlines in an hour. Lets go through it step-by-step:

    0. This is an image with teeth I wanted to get in vectorized format, each tooth separately:


    I have anaconda on my windows machine but if you have python with the general science tools (numpy, matplotlib, skimage, skipy) this code should work for you.

    1. Loading the image from the file. With imread we get a 3D numpy array. In the 3rd dimension are the RGB values:


    2. In the samples the algorithms where used on grayscale images, so firstr I had to convert the image to grayscale. This means I get a 2D array from the 3D one.

    If it's needed the image can be croped simply with array slice (e.g.: cropedimg = gimg[330:480, 50:480]) and with matplotlib the image can be displayed any time just calling imshow(gimg).

    3. Detecting the contours with skimage.

    As result we get an array containing the vector representation of all found contour lines separately. Let's display the results:

    4. For me the contour line was too detailed and rough so I wanted to have a more schematic result. With the tolerance parameter it's possible to set how detailed is the approximation. Finally we print an original and an approximated contour.